


Summary
AI cost should not be measured by token price alone. The real metric is the cost of each completed, validated unit of work, including model usage, error rates, re-prompting, human review, and the impact of poor outputs moving through a workflow.
John Briggs, CEO of Screendragon, explains how to calculate AI ROI per task, why different agents should use different models based on complexity and risk, and how orchestration layers like Screendragon AI Hub help control cost, quality, governance, and scale across multi-agent systems
Gauging Cost vs ROI: A Practical Framework
Token cost alone is a misleading metric. The right question is not what does this model cost per token but what is the cost per completed, validated unit of work.
A cheap model that fails 30% of the time and requires human review costs more than a premium model that gets it right consistently. The full calculation requires:
- Error rate — How often does the output need correction or re-generation
- Re-prompt rate — How many follow-up calls does it take to get a usable result
- Human review time — What does it cost in human hours to validate outputs
- Downstream impact — What is the cost of a bad output reaching the next stage of the workflow

Run this per task type, not across the whole system. Premium models are easily justified for high-stakes, low-volume tasks. Open source models at near-zero marginal cost are the right call for high-volume, well-defined tasks where the harness handles validation.
Two additional levers that change the unit economics dramatically:
- Batch processing discounts — Anthropic’s Claude Batch API delivers 50% discount on both input and output tokens for async workloads. For any task that does not need to be real-time, this halves your model cost immediately.
- Prompt caching — Up to 90% cost reduction on cached input tokens. For any agent with a consistent system prompt – brand guidelines, tool definitions, product context – prompt caching should be enabled by default.
Multi-Agent Systems: The Case for Per-Agent Model Selection
This is where most teams leave significant cost savings on the table. A multi-agent system is not one AI doing many things. It is a team of specialist agents, each with a clearly defined job. The critical insight is: each agent should be evaluated in isolation for its specific task.
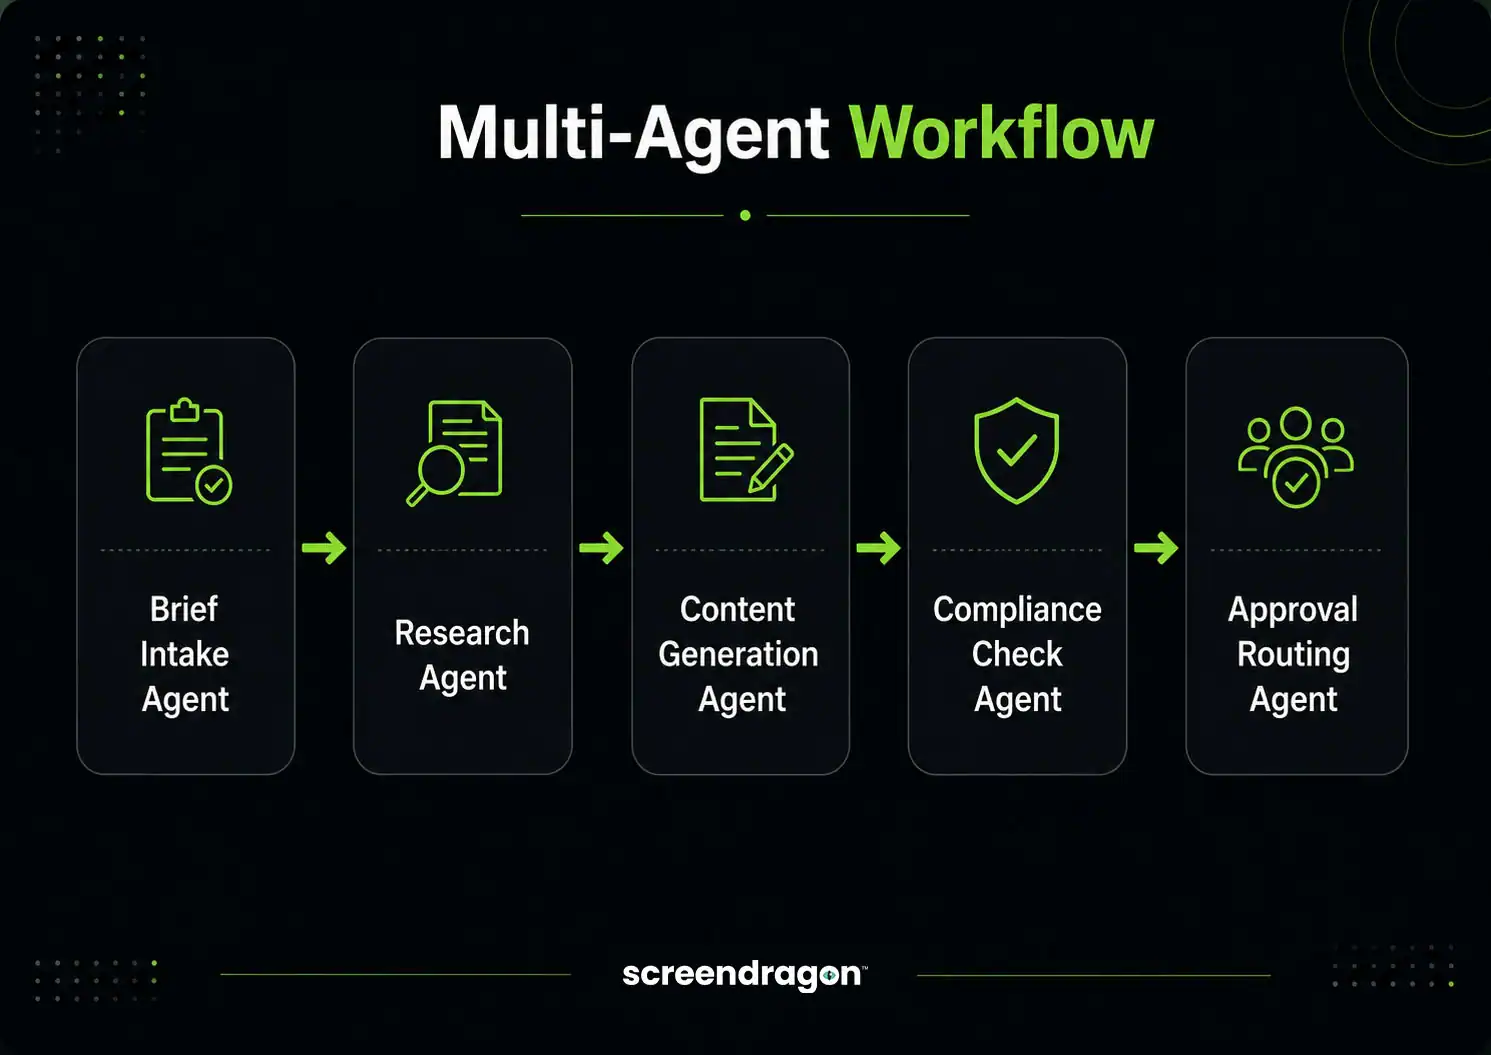
Each of these agents has a fundamentally different job with a different cost-quality tradeoff:
- Brief Intake Agent — Doing classification and data extraction. Lightweight task. Claude Haiku 4.5, Mistral Small 4, or Llama 4 Scout – a fraction of the cost of a premium model.
- Research Agent — Retrieving and synthesising information. Mid-tier with good retrieval. Command R+ or GPT-5.4 mini with RAG. The knowledge base does most of the heavy lifting; the model synthesises.
- Content Generation Agent — Producing the deliverable that goes to market. This is where quality directly affects brand perception. This justifies a premium model – Claude Sonnet 4.6 or GPT-5.4 mini depending on task complexity.
- Compliance Check Agent — Structured reasoning against defined compliance rules. High-stakes but well-defined. A fine-tuned or well-prompted mid-tier model works for most cases. Claude Opus 4.8 or o3 only for genuinely complex regulatory environments.
- Approval Routing Agent — Binary routing decision. The cheapest model that can follow instructions reliably. Claude Haiku 4.5 or Mistral Nemo.
When you route intelligently across five agents rather than sending everything to the most capable model, you can reduce total system cost by 60–70% with no reduction in output quality – because the quality-critical steps still use the right model, and the supporting steps do not.
Why the Orchestration Layer Matters as Much as the Models
All of the above – model routing, context management, knowledge retrieval, asset libraries, caching, self-correction loops – only works if you have an orchestration layer that can execute these decisions reliably in production, at scale, with full governance and auditability.
This is what Screendragon AI Hub is designed to do.
AI Hub is not a wrapper around a single model. It is a governed execution environment built on the insight that the LLM is one component in a larger system. It enables you to:
- Define agents with different models for different tasks – mix GPT-5.4 nano for classification, Claude Sonnet 4.6 for content generation, and a self-hosted SQLCoder instance for database queries, all within a single workflow
- Inject the right knowledge from structured knowledge bases at the right point in execution – reducing token cost while improving accuracy
- Embed approved asset libraries that agents retrieve and compose from rather than generate from scratch – ensuring consistency and compliance by design
- Route tasks based on complexity, urgency, and cost thresholds – dynamically selecting the appropriate model tier for each execution
- Run self-correction loops that validate outputs against compliance rules before they exit the system
- Swap models as the landscape evolves without rebuilding workflows – because the workflow logic lives in the harness, not tied to any specific model API
Screendragon’s AI Hub
With Screendragon’s AI-Hub, organisations can create repeatable agentic workflows. The agent knows what it is responsible for. It knows what knowledge it can use. It knows the rules it needs to follow. It knows how its output should be structured.
Our AI Hub gives teams a secure, enterprise-grade environment to create and manage AI agents within Screendragon workflows. Agents can be built around specific roles, tasks, tools, triggers, rules, knowledge sources, and output formats.
That gives teams more than speed. It gives them consistency, with repeatable outputs that can be scaled.
A briefing agent can help create better briefs faster. A proofing agent can flag inconsistencies or missing details. A resourcing agent can recommend assignments based on skills, availability, and workload. A compliance agent can check work before it moves too far downstream.


